Skip to content

research software engineer · lima · remote

Code as craft. Data as evidence.

I build data pipelines, scrapers and web tools for research and business, and I document the decisions so anyone can audit them.

View projects

16 projects · 8 live

Projects

Case studies with the source and the numbers behind them.

Live · Usable

Science & bioinformatics

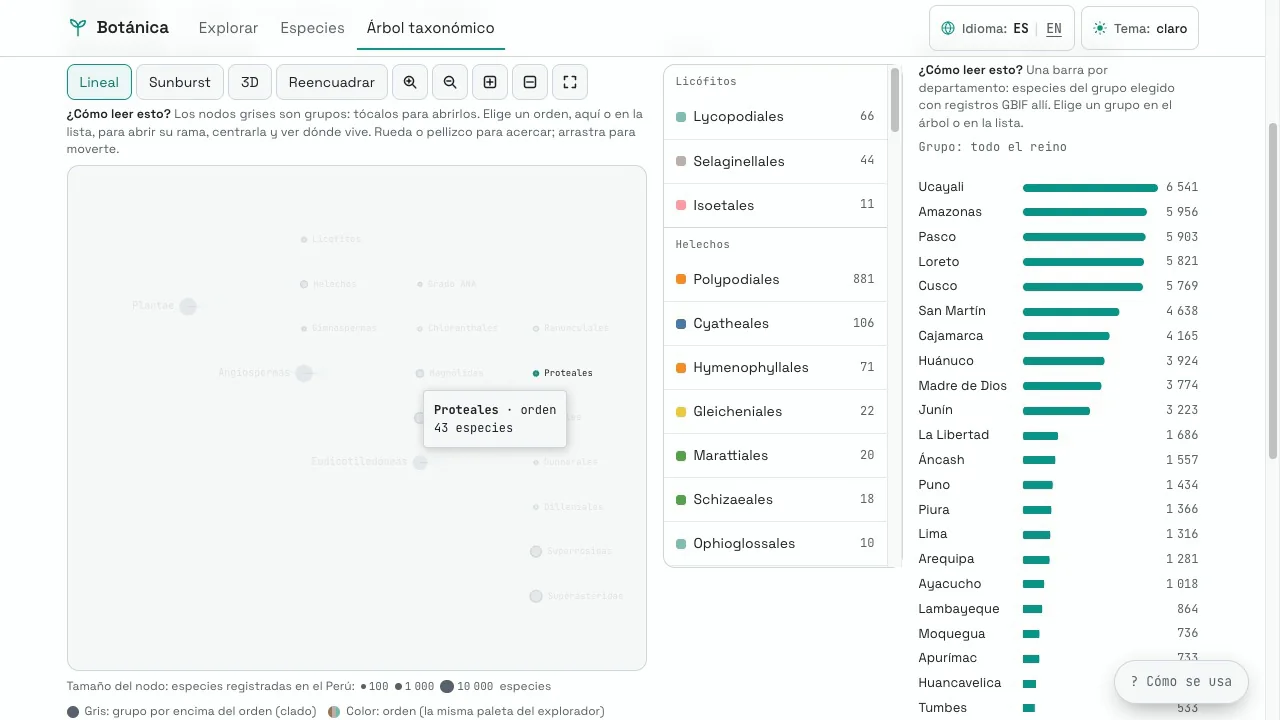
Atlas Botánico del Perú

I turned raw GBIF data into a tree of Peru's 21,585 accepted plant species that opens in the browser.

DuckDB · 1.28M GBIF records · ten-stage ETL · static marts, no backend
Case study
Live · Usable
Free-tier Streamlit apps sleep when idle; the first visitor wakes them, which can take about a minute.

Machine learning & AI

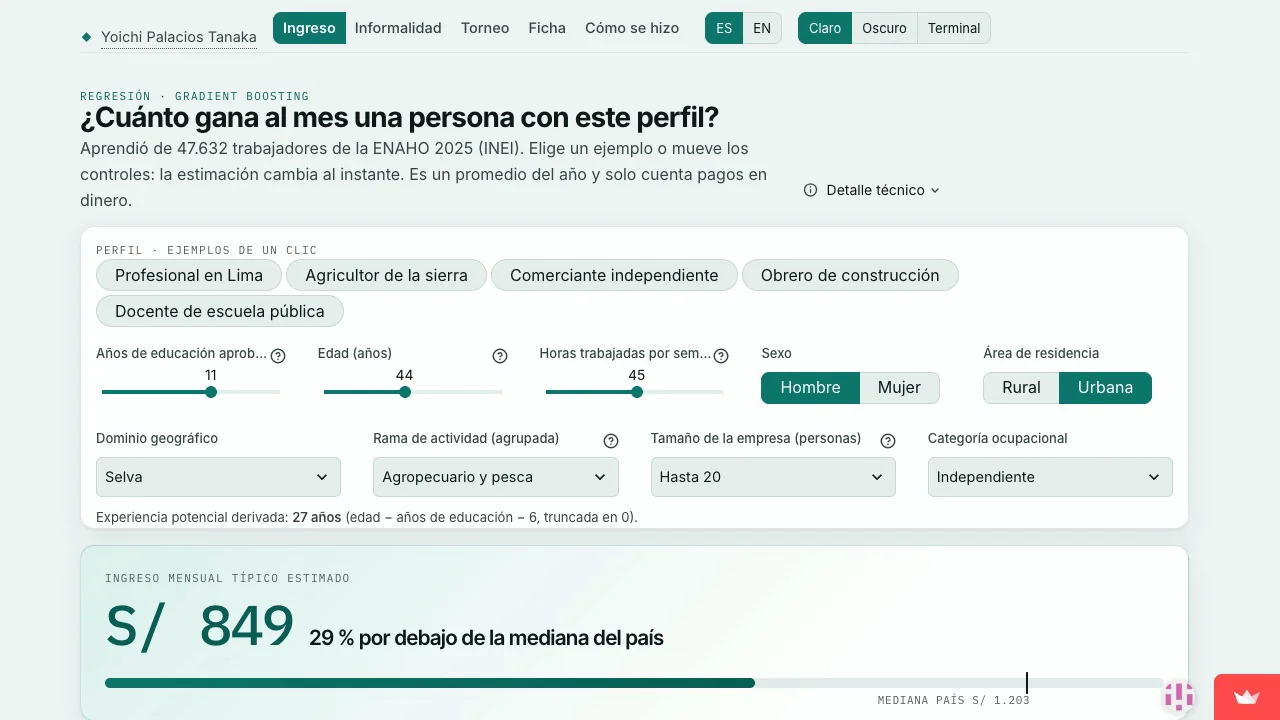
Predictor de Ingresos e Informalidad

I compared 9 model specifications to predict labor income and informality risk in Peru, from the ENAHO household survey.

scikit-learn · nine-model tournament · statsmodels intervals · Streamlit

  • scikit-learn
  • pandas
  • Streamlit
  • statsmodels
  • Python
Case study

All 16 projects →

Being moved to public

OpenMetadata Warehouse
In development · Prototype

Infrastructure & servers

OpenMetadata Warehouse

I connected Claude Code to an OpenMetadata service running over an Oracle and SQL Server warehouse, so ingestion, lineage and server lifecycle are managed as code.

OpenMetadata · Oracle · SQL Server · Python · Docker

  • Oracle
  • SQL Server
  • Python
  • Docker
  • +1
Case study
Open Data Repository
In development · Prototype

Data & public sector

Open Data Repository

I'm turning a folder of scraping and cleaning scripts into a static catalogue anyone can search, preview and use offline.

Python · SQLite · static site, no server

Workboard
In development · Prototype

Web & product

Workboard

A Jira-style board: projects, epics, cards, timeline — built for a public-sector IT office.

JavaScript

Case study
Signal Agent
In development · Prototype

Agents & AI automation

Signal Agent

A market monitor where the model has to write a falsifiable prediction before it can be scored — 3 open, 0 resolved, the first ones due January 2027.

Python · GitHub Actions · SQLite

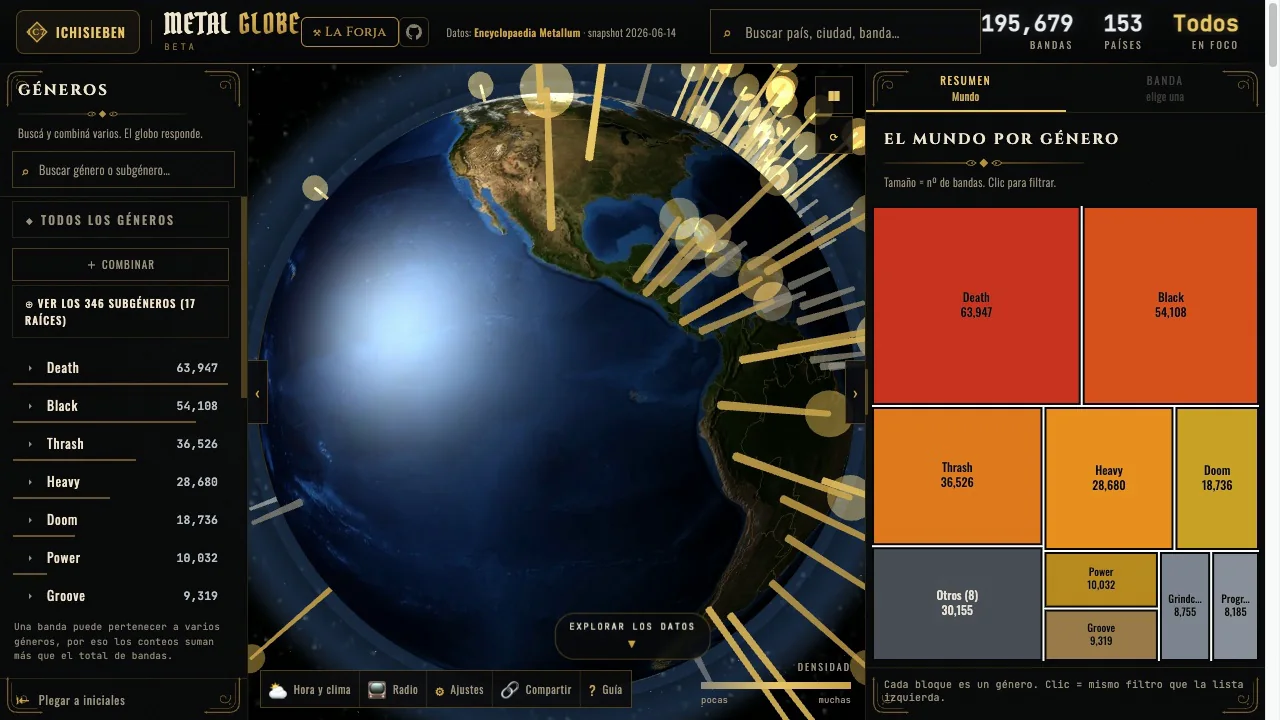
54 tools · picked per problem

Stack

The tools I work with, grouped by area. Versatility isn't piling up frameworks — it's picking the right one for each problem.

See the map →

Languages 06

Frameworks 07

  • Astro 2 projects Generates static sites that ship zero JavaScript except where explicitly opted in.
  • Vite 2 projects Build tool and dev server, fast even in projects with many modules.
  • React 1 project Component-based UI library; the base of almost any modern interactive frontend.
  • Streamlit 1 project Turns a Python script into an interactive web app without writing frontend code.
  • Zustand 1 project Minimal state management in React, without heavier alternatives' boilerplate.
  • Tailwind CSS Utility-class CSS: designing without jumping between stylesheet files.
  • PyQt6 Desktop interfaces in Python, used when the app cannot live in a browser.

Data 12

  • SQLite 4 projects Relational database embedded in a single file, no server to administer.
  • Apache ECharts 3 projects Interactive charts for dashboards with real data volume.
  • Three.js 2 projects 3D in the browser over WebGL, for visualisations and interactive scenes.
  • DuckDB 1 project Embedded SQL engine for analysing large files (Parquet, CSV) without standing up a server.
  • ETL 1 project Extracting, transforming and loading data from a raw source into something queryable.
  • pandas 1 project Table manipulation in Python: cleaning, grouping and transforming data before analysis.
  • Oracle 1 project Relational database used in large, long-lived enterprise systems.
  • SQL Server 1 project Microsoft's relational database, common in Windows-based enterprise systems.
  • Parquet Columnar, compressed file format built for analytics over large volumes.
  • Polars A pandas alternative written in Rust, much faster on large datasets.
  • Excel & reporting Reports and spreadsheets when the final audience lives in Excel, not a dashboard.
  • MySQL Open-source relational database, the most common one on shared hosting.

Infrastructure & servers 05

  • Git 3 projects Version control: history, branches, and the base of any code collaboration workflow.
  • Static hosting 2 projects Serving sites with no backend: faster, cheaper, smaller attack surface.
  • Data catalog: lineage, ownership and discovery across an organisation's sources.
  • Docker 1 project Packages an app with everything it needs to run the same on any machine.
  • Airflow Orchestrates data pipelines as task graphs with dependencies and retries.

Operating systems 04

  • Windows 2 projects Desktop operating system, the most common development and verification environment.
  • macOS 2 projects Building and verifying on Apple Silicon, Apple's current hardware architecture.
  • Ubuntu Server 1 project The server edition of Ubuntu, a Linux distribution.
  • Linux 1 project The operating system behind almost everything deployed on a server.

Security 02

  • Secrets management 1 project Credentials out of the repo, always via environment variable, audited before publishing.
  • Data privacy Synthetic or public data in demos: no identifiable real person.

AI & machine learning 09

  • LLMs & agents 3 projects Language models orchestrated as agents, with evaluation built into the flow, not the pitch.
  • scikit-learn 1 project Classic machine learning models: classification, regression and clustering.
  • statsmodels 1 project Classic statistical models in Python: regressions with inference, not just prediction.
  • PyTorch Machine learning framework for training and running deep learning models.
  • OpenCV Computer vision library: detection, transformation and image processing.
  • InsightFace Open-source face detection and recognition, handled carefully since it is biometric data.
  • OCR & documents Turning scanned documents or images into text that can be searched and processed.
  • Segment Anything (SAM) Meta's image segmentation model: cuts out any object with no prior training.
  • Speech-to-text Transcribing audio to text to search, index or caption spoken content.

Scraping & automation 06

  • Scraping 3 projects Extracting data from undocumented APIs or HTML, always from legitimate sources.
  • GitHub Actions 3 projects CI/CD hosted in the same repo: build, test and deploy on every push.
  • Playwright 2 projects Automates a real browser to test sites or extract data that needs JavaScript.
  • Entity matching 1 project Deciding whether two different records describe the same entity, by text, code or image.
  • BeautifulSoup & selectolax 1 project HTML parsers for pulling data out of pages that have no API.
  • Selenium Browser automation for testing or scraping when a site needs real interaction.

Business 03

  • Open data 2 projects Building with public, citable sources instead of client data.
  • Data visualization 1 project Making a huge catalogue understandable in 30 seconds: the discipline of showing data.
  • E-commerce 1 project Catalogue, cart and checkout: the mechanics of a shop, not just the storefront.

the reasoning, not the pitch

How I work

IchiSieben is the working name of Yoichi Palacios Tanaka. I build data pipelines, scrapers and web tools — the kind of software that reads a source, cleans it, and turns it into something a person can act on.

Every project here ships with the decisions behind it written down: why this database and not another, what the data actually shows, what I would change next. That's not a courtesy — it's how the work gets checked, by me or by anyone else.

I use AI where it earns its place: to move faster through boilerplate, to explore a dataset, to draft the first pass. The judgement on what to build and whether it's right stays mine, and the README says so.

one email, no form

Contact

A project, a role, or a stack question? Pick what fits and I'll get the right context first.
GitHub @IchiSieben